AI attacks don't break your systems. They persuade them. Here's what 26 weeks of AI threat reports reveal, and how to break the AI Kill Chain.
AI attacks don't look like traditional attacks. There's no malware to catch, no vulnerability to patch, no signature to match. For CISOs, CIOs and CEOs, the new risk is software that does exactly what it was told, by the wrong person.
It's already costing companies. IBM's 2025 Cost of a Data Breach report found that 13% of organizations had suffered a breach of an AI model or application, and 97% of those had no proper AI access controls [1] (When AI Is Breached, Access Control Is the Blind Spot).
With Agentic AI - the front door is open
Agentic software has eliminated the restricted input field. Users type in any language they want, and language is open to interpretation: each reading can be right in its own context. That makes an agent easy to steer by rephrasing a request or shifting its context. Add hidden characters, documents with obfuscated content and planted instructions, and you get reasoning compromise.
With Agentic AI - the back door is open too
Skills instruct agents silently. Developers download them to automate work, and agents load them to learn new actions. Agents talk to other agents, to LLMs that interpret their instructions, and to MCP servers that feed them data with few constraints. Lineaje projects that in 2027, AI agents will generate more code, much of it written and run on the fly at runtime, than human developers push through CI/CD, with no one reviewing it. The signs are already here: 75% of new code at Google is AI-generated [2], and enterprise AI agents are forecast to grow from 28.6 million in 2025 to more than 2.2 billion by 2030 [3], against about 36.5 million professional developers worldwide [4].
That supply is already contaminated. Of 52,755 skills Lineaje analyzed across major marketplaces, 2.1% were unsafe, and 62.9% of those were confirmed malicious (Silent AI Attackers: Are They Already in Your Environment?). By malware standards, that rate is exceptionally high. A single malicious skill packs an average of 9.4 attack categories (AI Skills Are Becoming the Swiss Army Knife of Attack). Developers and agents can't spot them, MCP servers can be compromised, and these back-end attacks are far harder to detect and prevent.
Traditional security asks "what was exploited?" In AI incidents, the honest answer is often "reasoning." Reasoning is not an asset that a SOC can point to after the fact and remediate.
Four forces, one new attack surface
Agents are everywhere, often without IT knowing. Gartner expects 40% of enterprise apps to include task-specific AI agents by the end of 2026, up from under 5% in 2025 [5]. And 45% of employees now regularly use AI on corporate devices, up from 15% a year earlier [6].
Attacks are poisoning the AI supply chain at scale by targeting agents. Lineaje's Malicious Open-Source Software Scanner checked a million versions of the most popular npm and PyPI packages and flagged 1.6% as malicious or suspicious. About 9% of the flagged packages are AI-themed, and a third of them carry prompt-injection payloads written for the AI that reads the code, not the human.
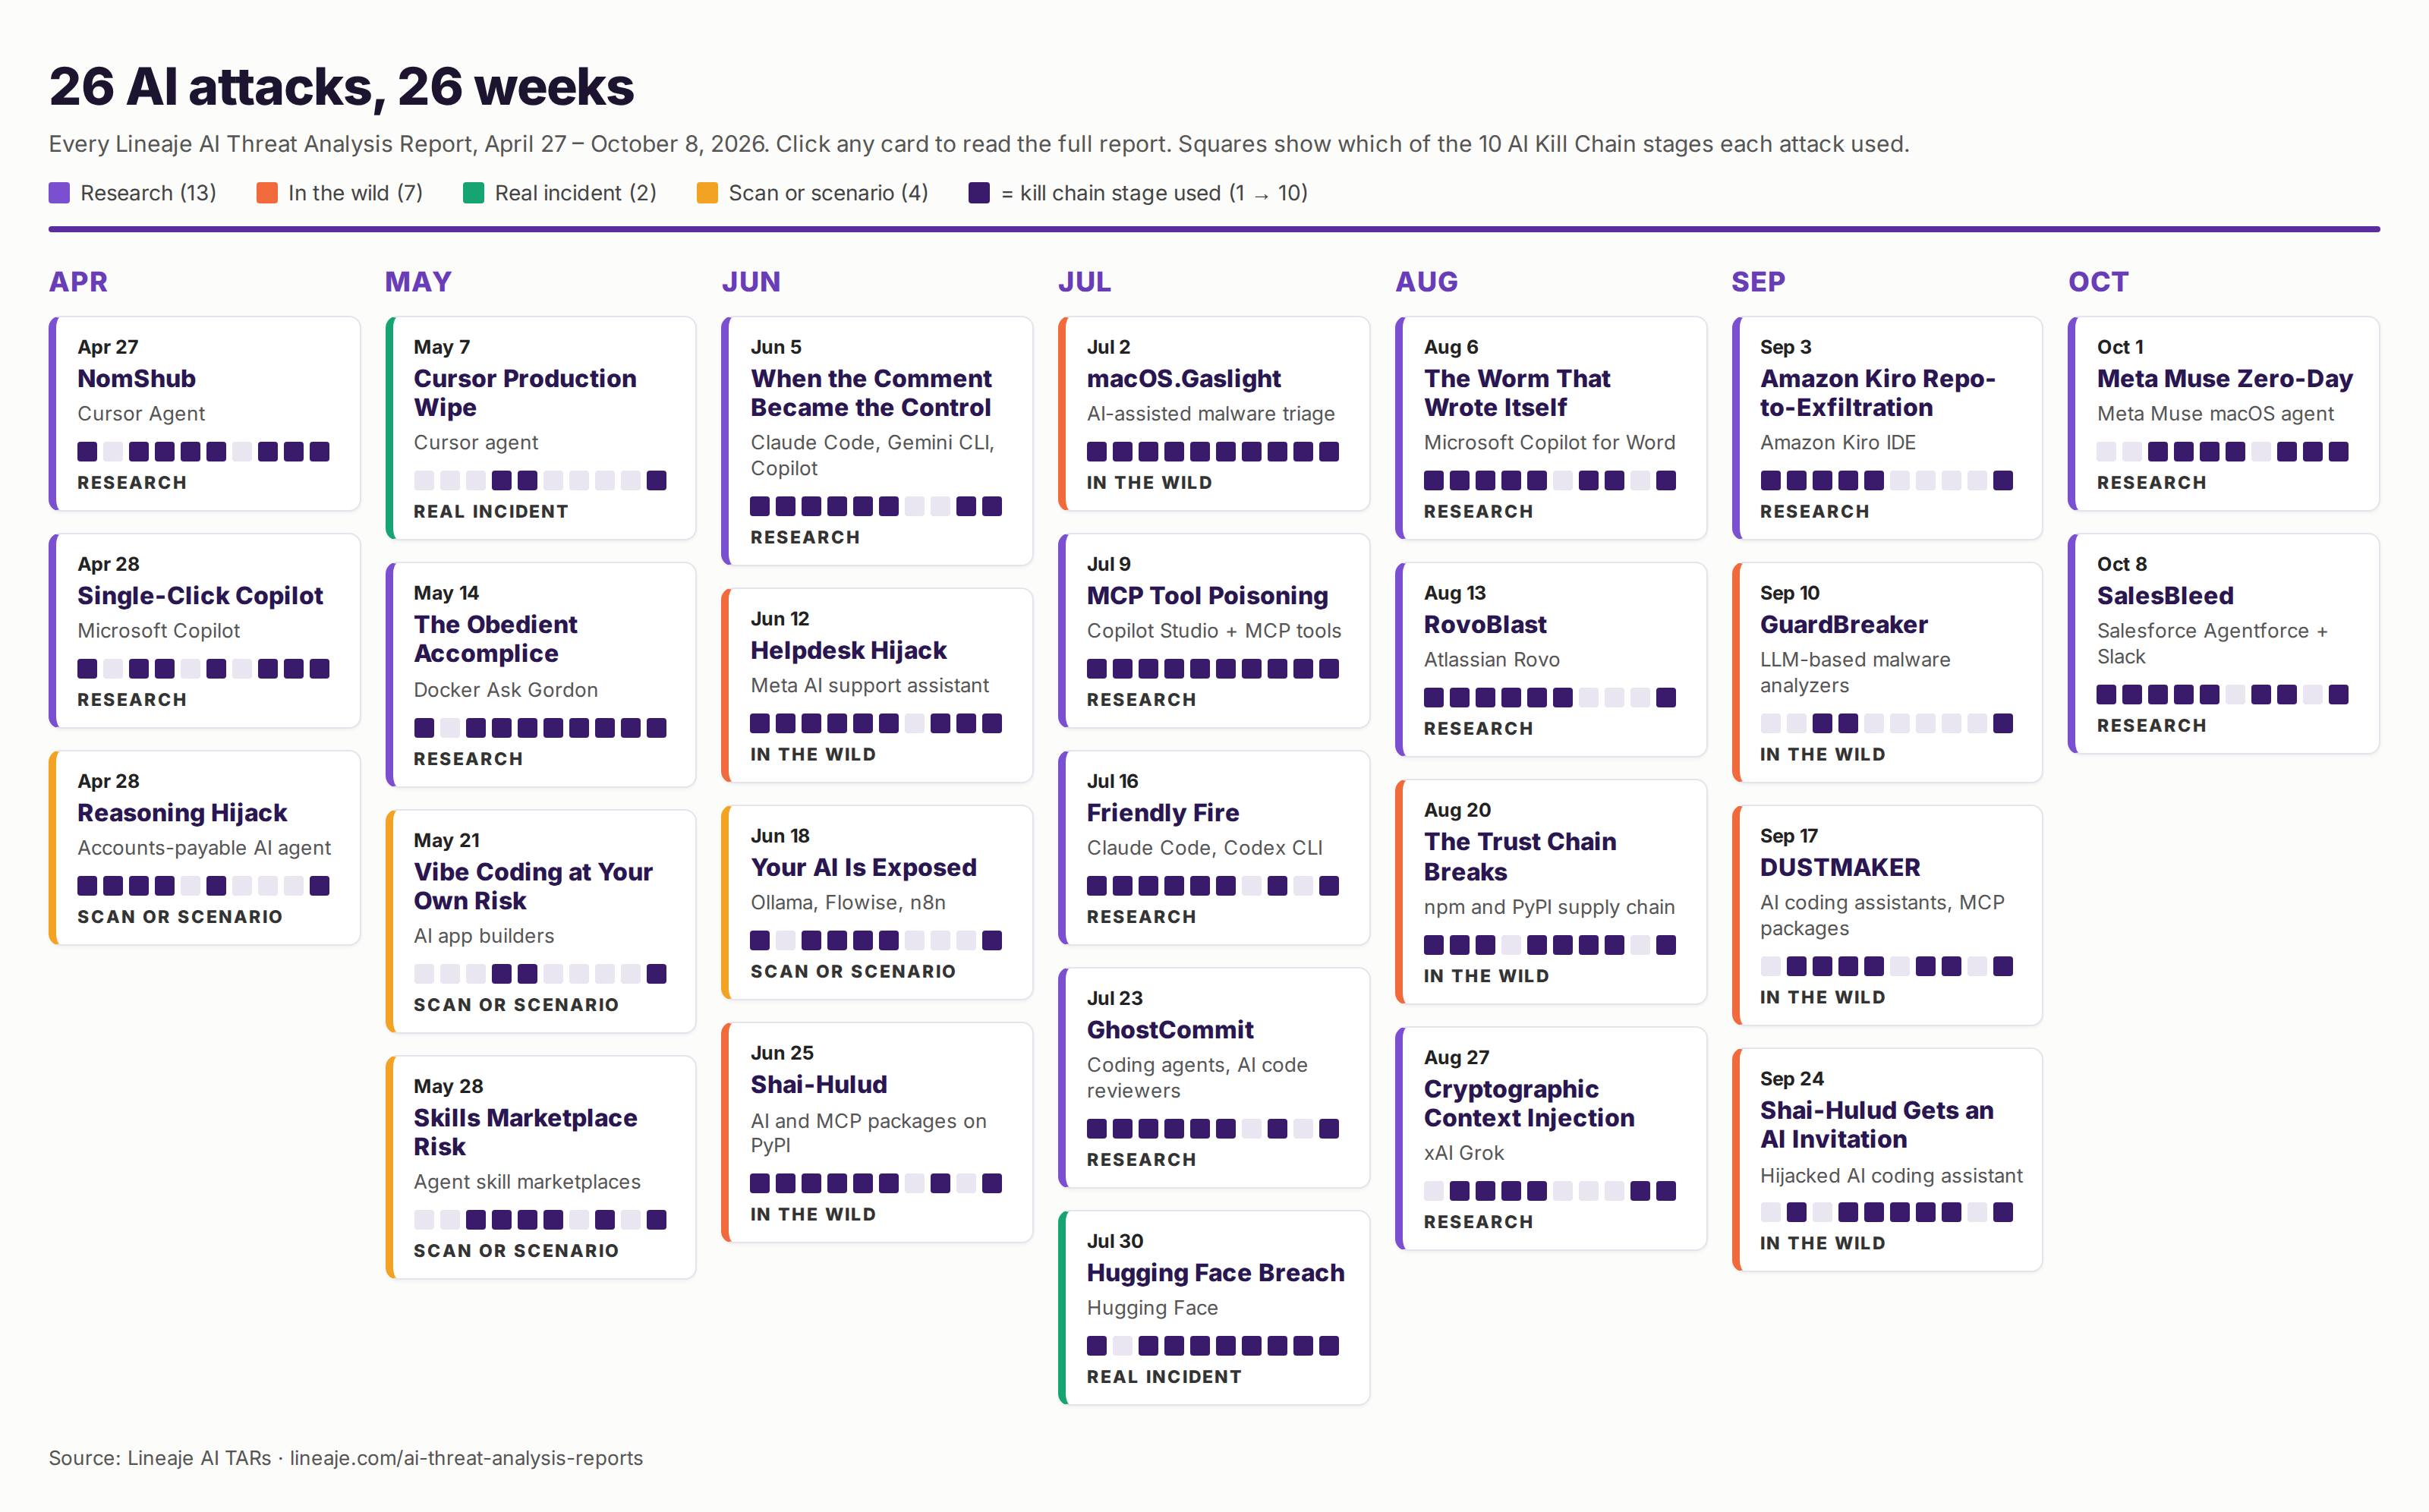
Attackers target the AI inside developer tools. In May, the Mini Shai-Hulud worm planted persistence files in .claude/ and .vscode/ folders [7]. In September, our DUSTMAKER AI TAR showed TeamPCP using the same folders to turn coding assistants into an execution engine.
Frameworks are racing to catch up. OWASP published its Top 10 for Agentic Applications in December 2025 [8], MITRE ATLAS added agent tool-poisoning techniques this year [9], and EU AI Act transparency duties took effect on August 2, 2026 [10].
What 26 weeks of AI threat analysis reports reveal
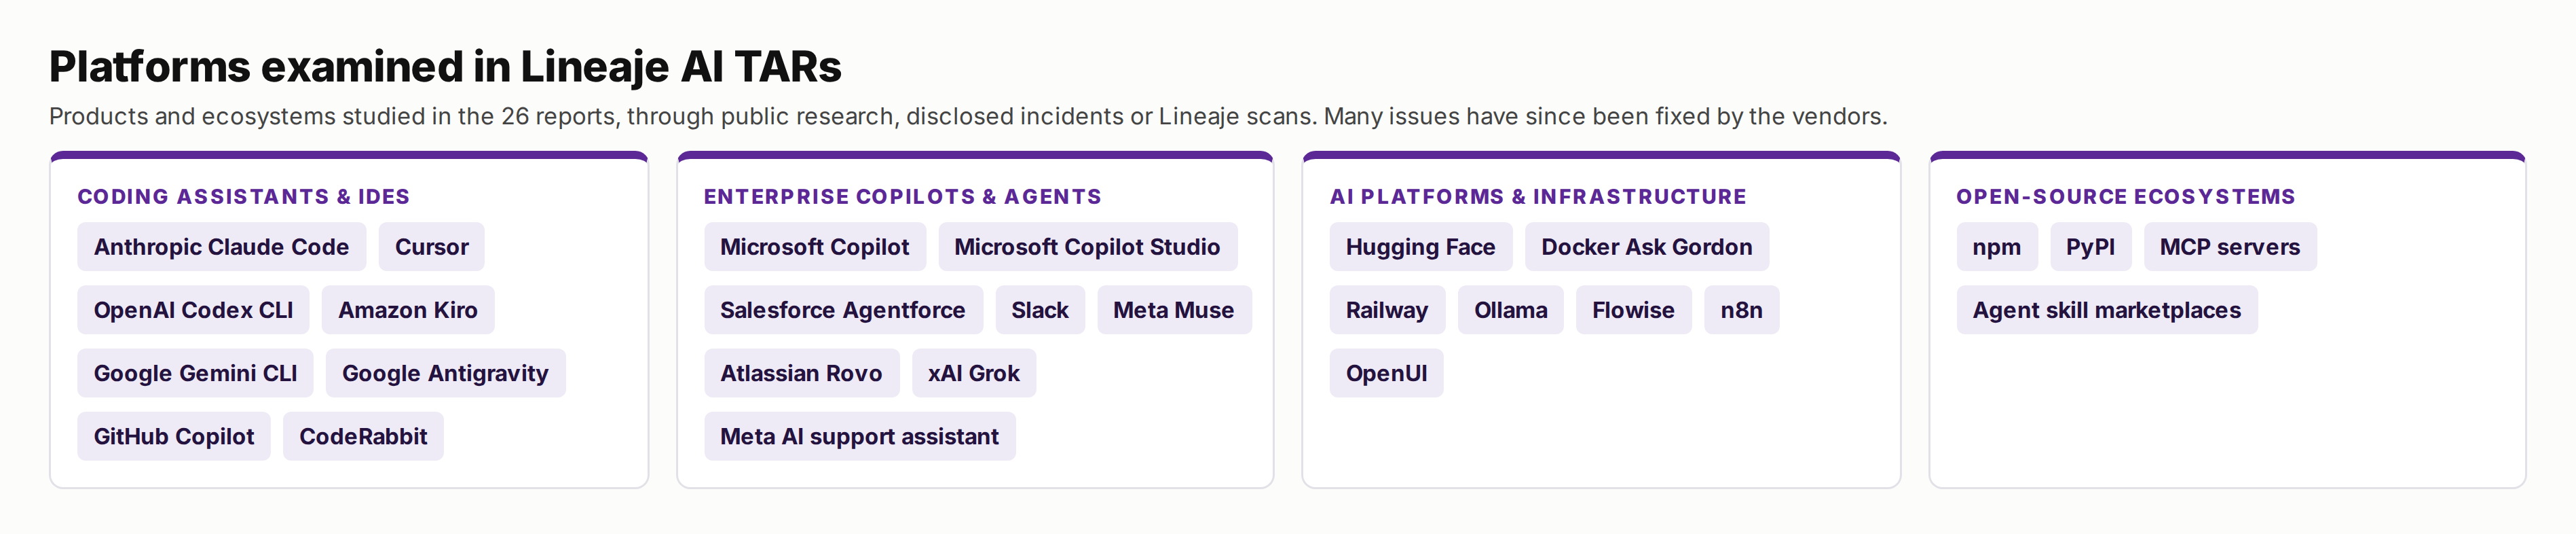
Since April 2026, Lineaje has published an AI Threat Analysis Report (AI TAR) every week. Each breaks down a real attack or disclosed technique and maps it to the kill chain. The 26 reports so far span the AI stack, from coding assistants and enterprise copilots to AI platforms and the open-source ecosystems beneath them.
Figure 2. Platforms examined in the 26 AI TARs, through public research, disclosed incidents or Lineaje scans. Many issues have since been fixed by the vendors.
AI attacks are different: similar stages, new techniques
They reason. They produce a likely answer, not a verified one.
They operate on untrusted input. Prompts, documents, emails, tickets and web pages all flow in.
They act with delegated authority. They call real tools, APIs and payment systems.
They remember. State persists beyond a single interaction.
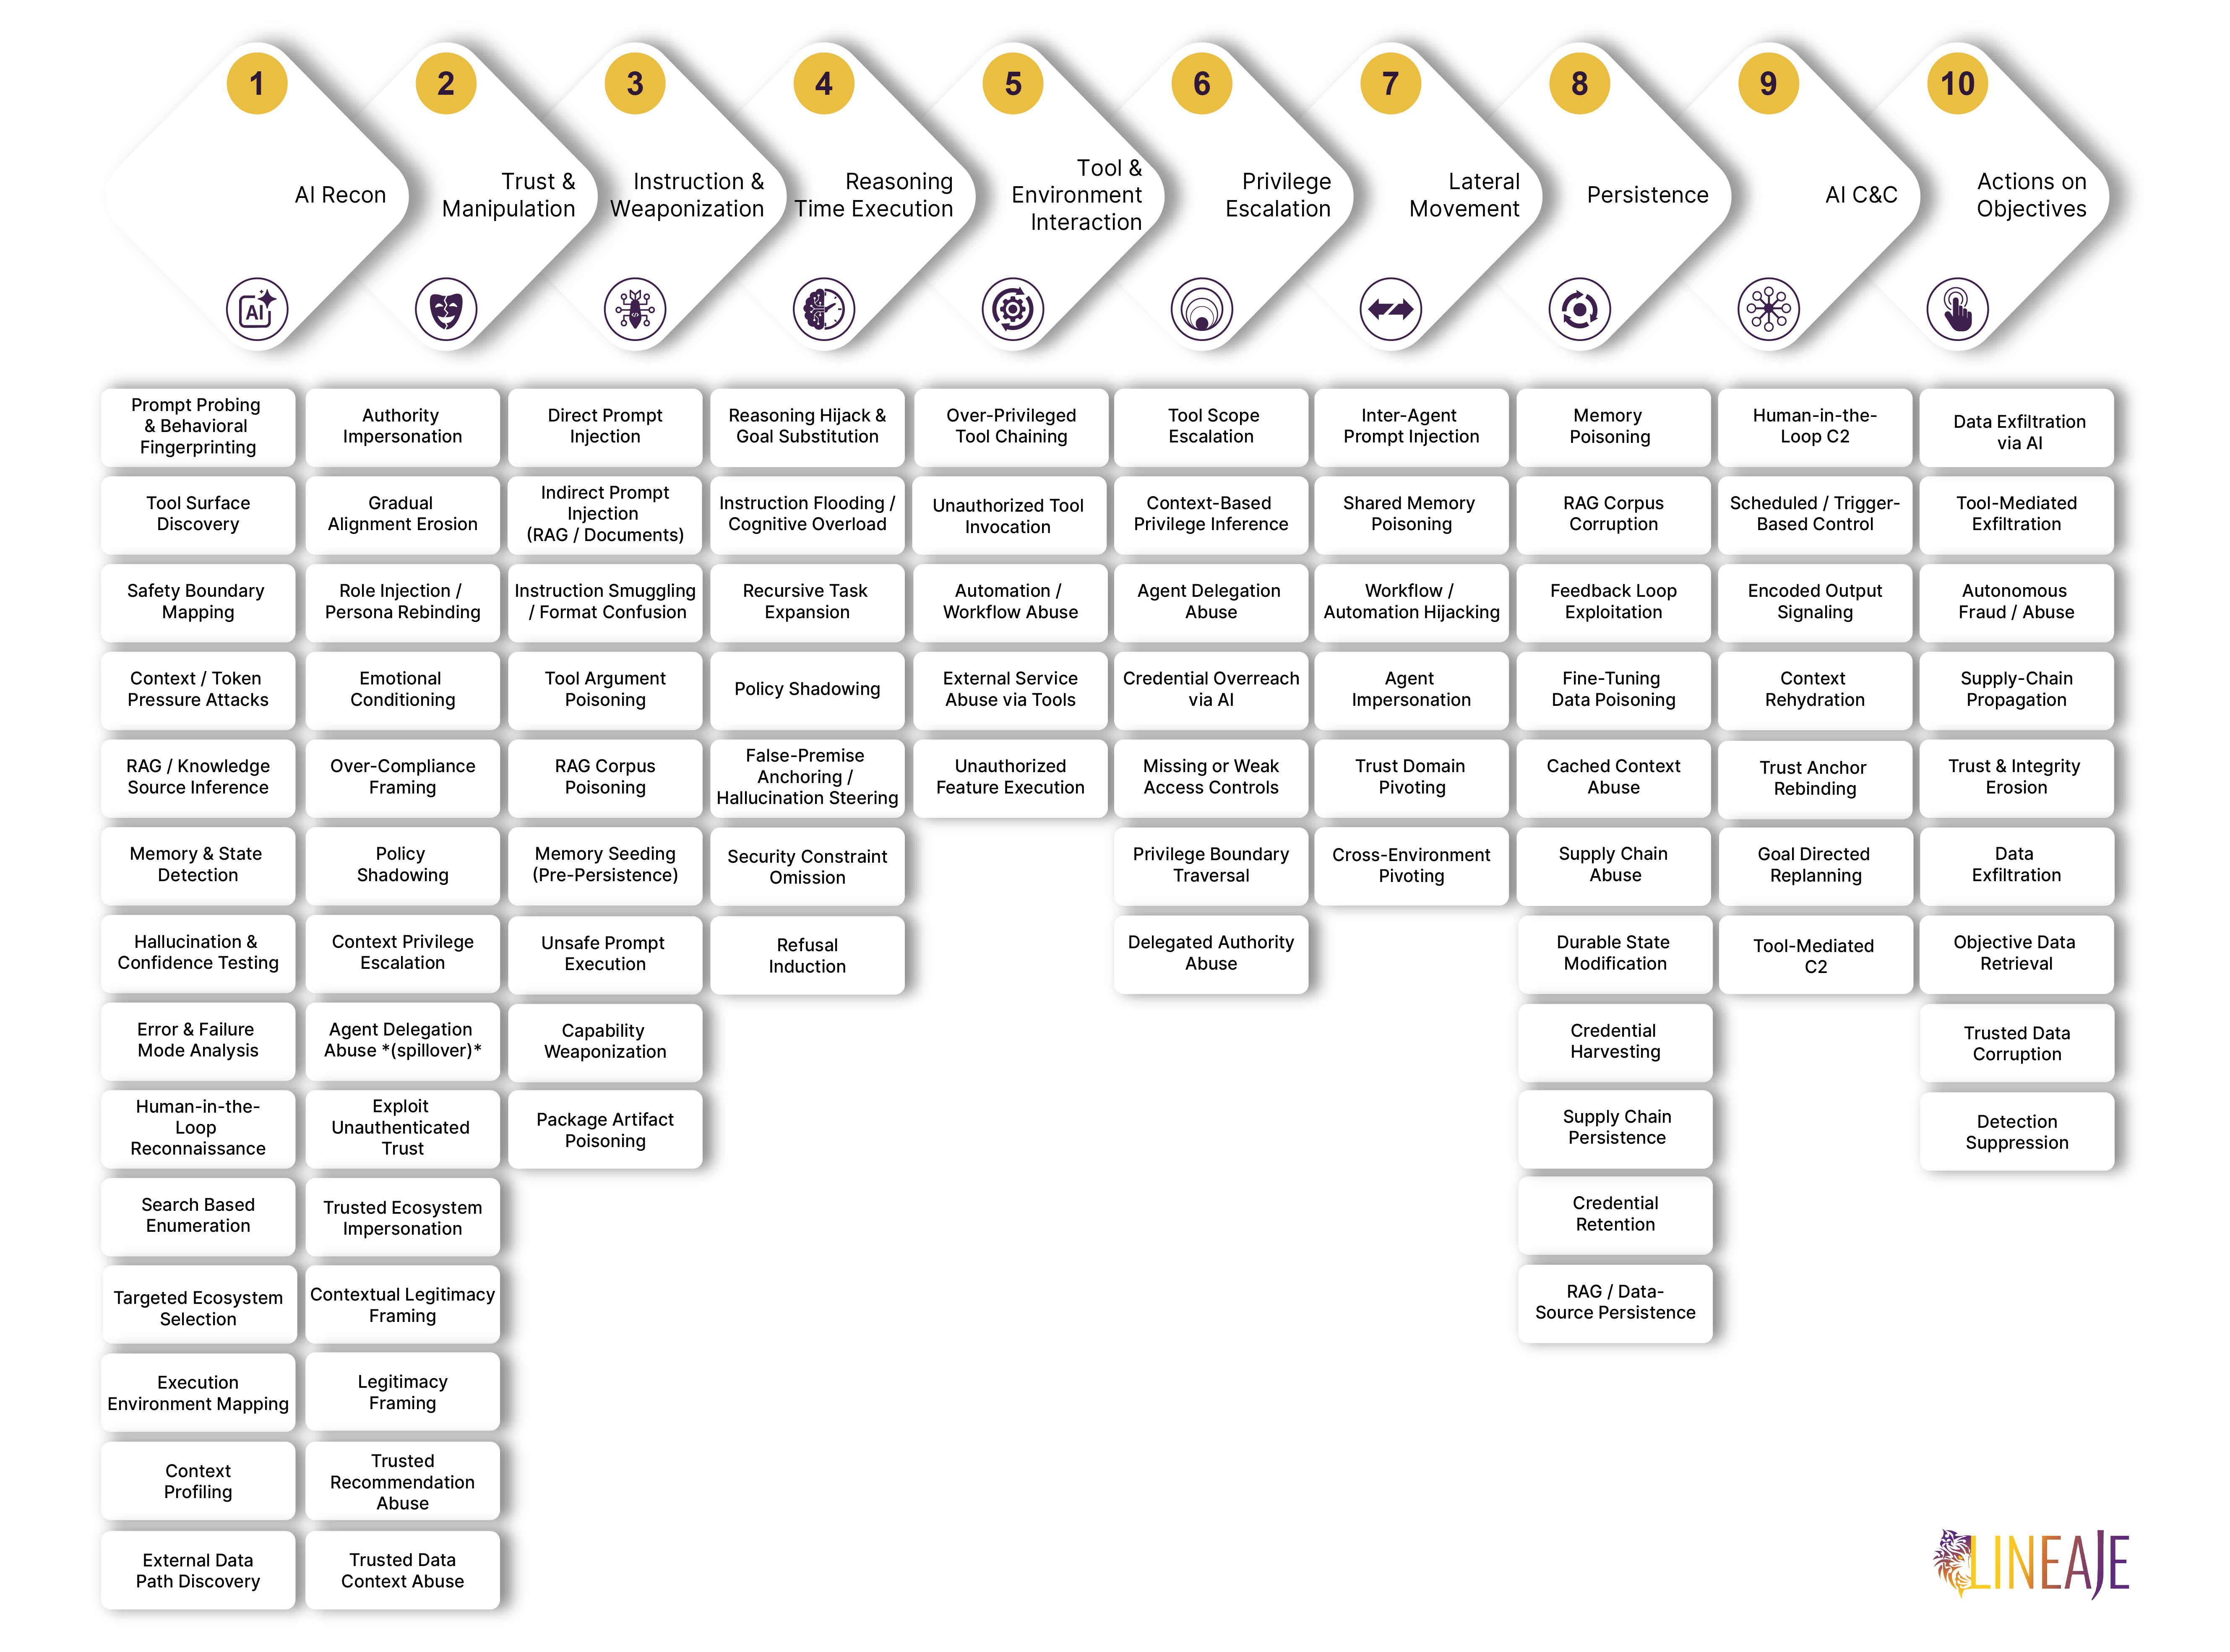
So AI attacks don't need vulnerabilities. They use capability chaining, where each normal capability enables the next. The Lineaje AI Kill Chain maps that progression in ten stages [11].
Stage
What happens
1. AI Reconnaissance
The attacker maps the model's behavior, boundaries and failure modes
2. Trust Establishment & Manipulation
The model is conditioned to comply
3. Instruction / Input Weaponization
Language turns into control
4. Reasoning Time Execution
Thinking becomes execution: the AI equivalent of an exploit
5. Tool & Environment Exploitation
Reasoning turns into real action
6. Privilege Escalation
Authority expands by inference, not credential theft
7. Lateral Movement
Trust spreads beyond its boundary
8. Persistence
The AI remembers the wrong things
9. AI-Native Command & Control
Control through meaning, not network beacons
10. Actions on Objectives
Harmful actions pass as legitimate
Table 1. The ten stages of Lineaje AI Kill Chain
Figure 3. The Lineaje AI Kill Chain: 10 Stages and 55 AI attack techniques. Explore the interactive version at https://www.lineaje.com/ai-kill-chain.
What we learned: Building secure agents is necessary; runtime agentic security cannot work without build-time inserted constraints
Most AI incidents use no malware, exploit no vulnerability, and trigger no alert. They come from ambiguous goals, over-broad authority, unbounded memory, and implicit trust. Those are design decisions, best fixed before deployment.
Design-time controls aren't enough on their own, though. Agents meet new prompts, documents, and tools on every run, and runtime-only detection detects but acts too late. Reaction is not an approach that works well; built-in security is better.
The answer is both: guardrails built in at design time and enforced at every step while the agent runs.
Stages 1–4, early: the strongest place to break the chain. Approved models, authentication, separating data from instructions, and goal integrity. Break it here and the later stages never happen.
Stages 5–7, mid-chain: contain the damage. Tool allowlists, intent-bound authorization, credential caps, and authenticated agent-to-agent traffic.
Stages 8–10, late: stop the action. Once poisoned data persists or money moves, recovery is slow and costly. A runtime check has to stop the action before it completes.
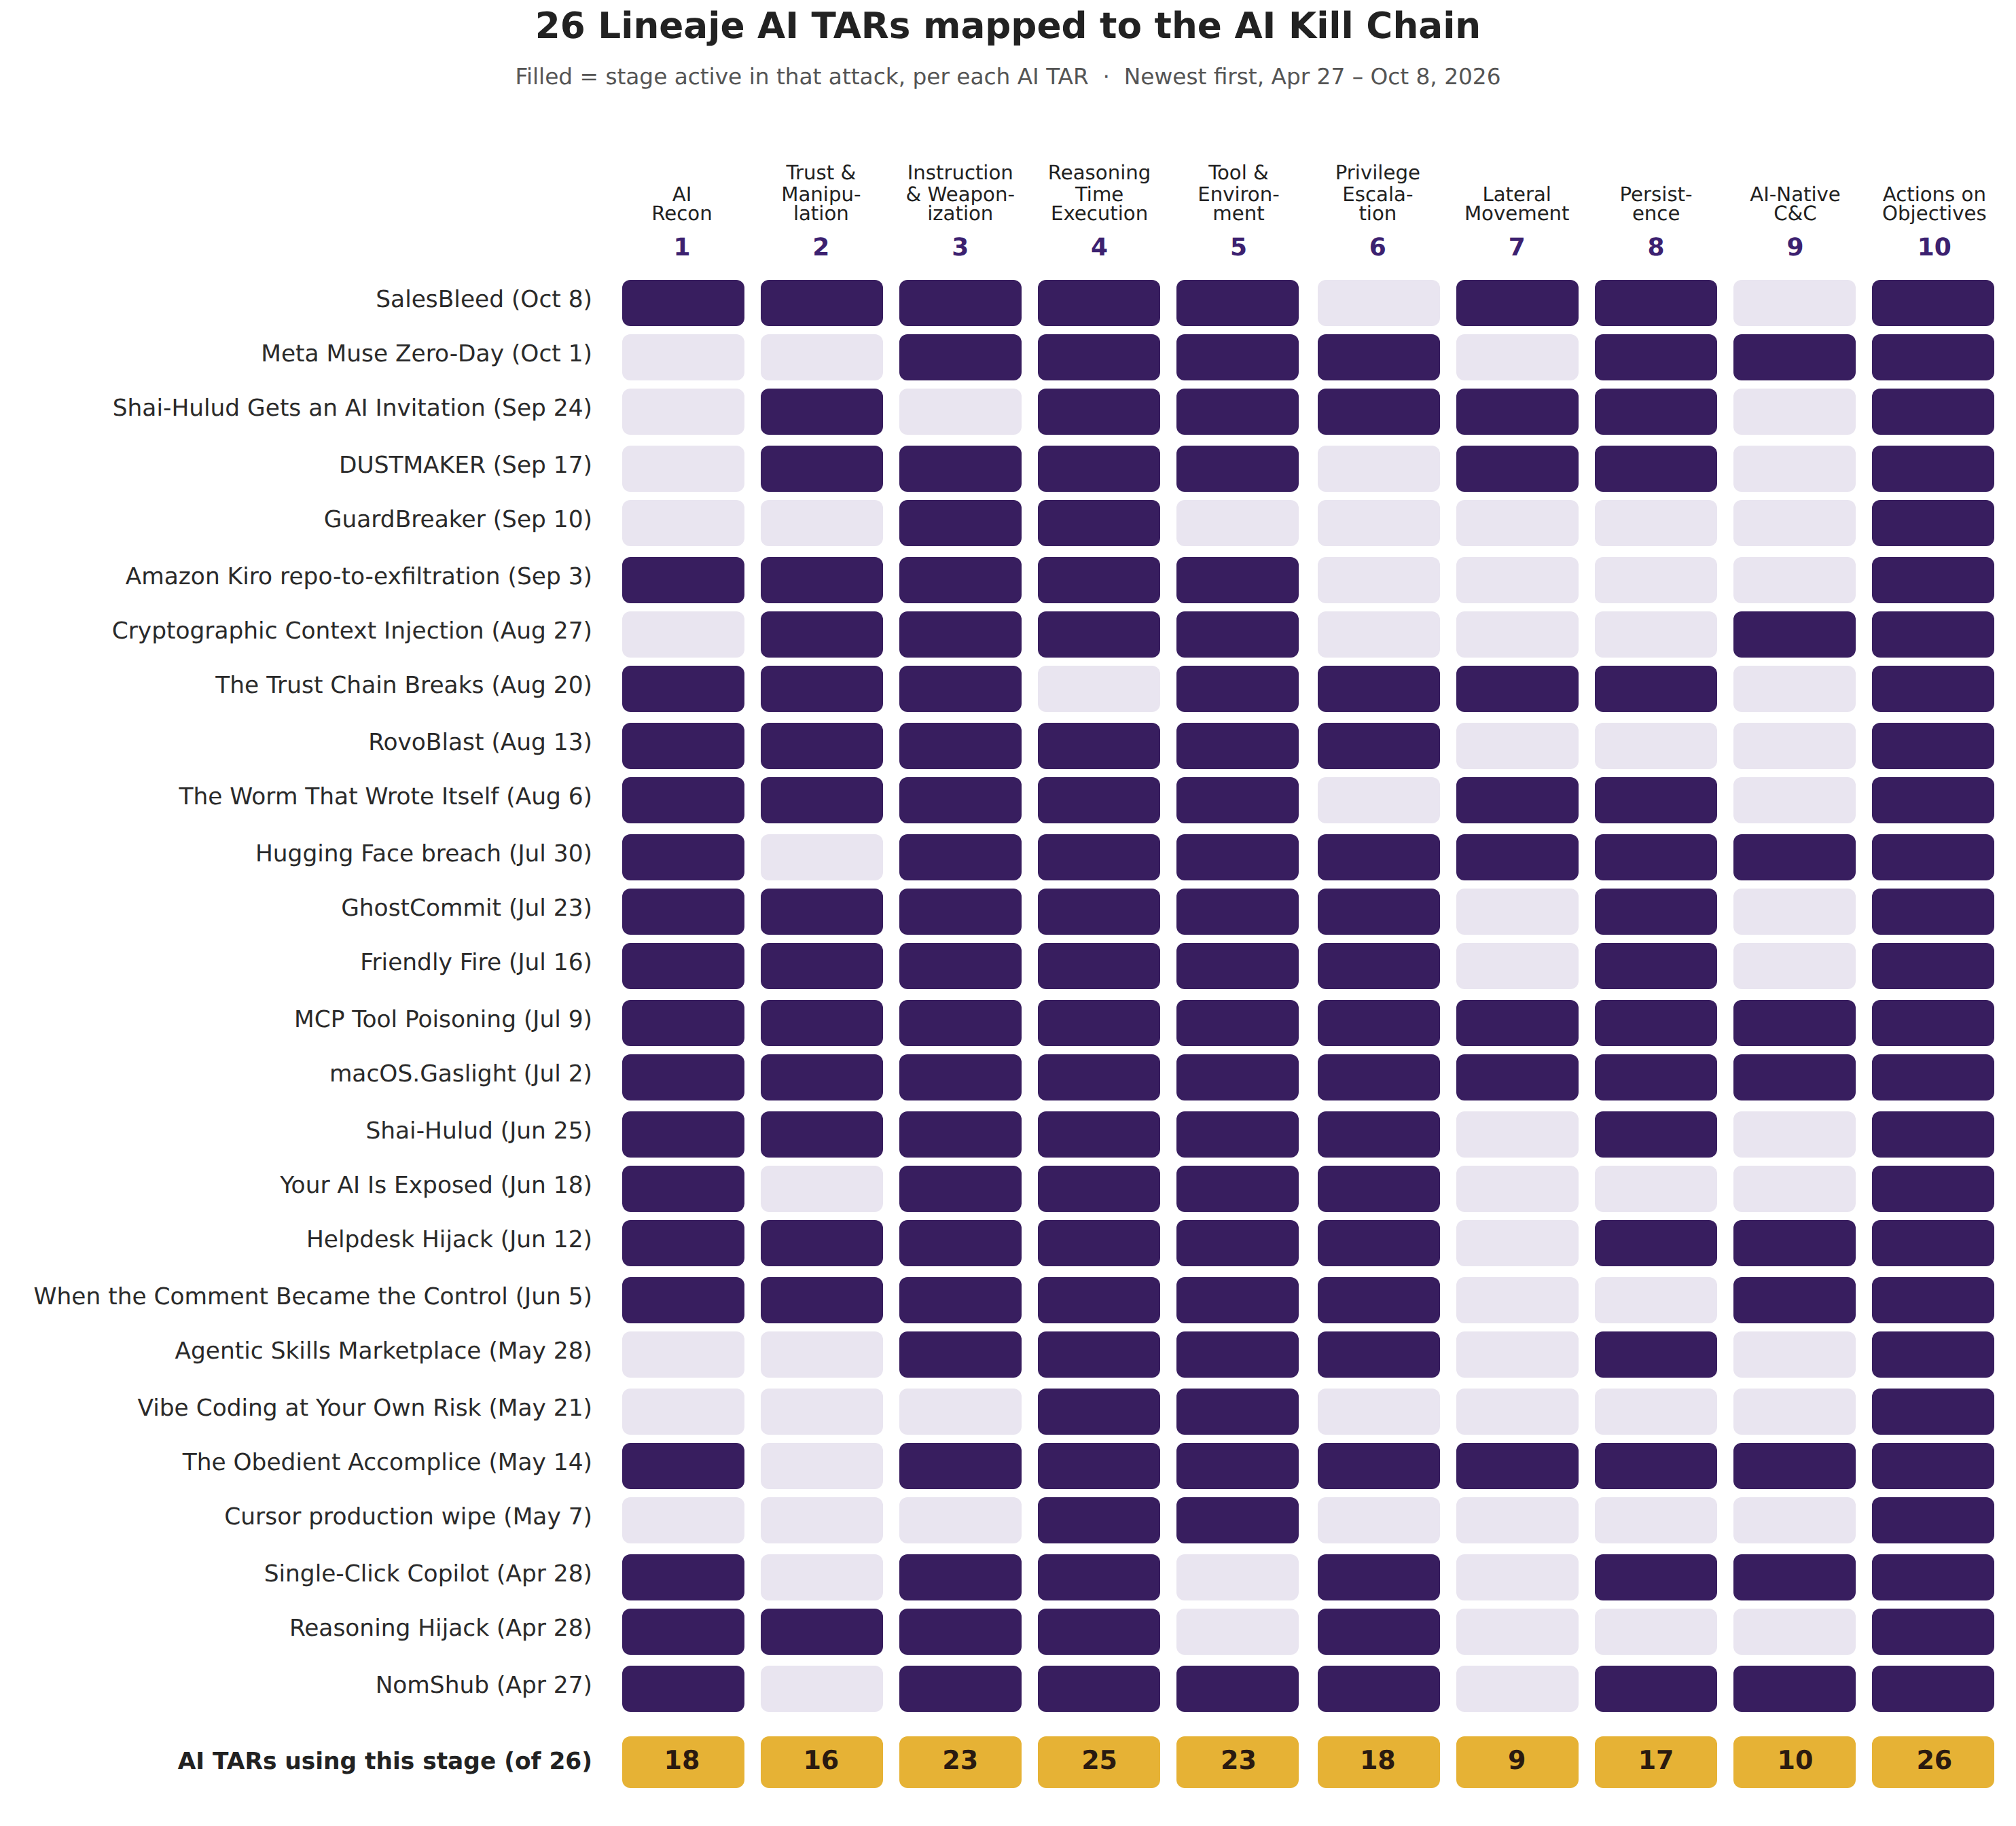
Zooming out across all 26 attacks shows which stages attackers rely on most.
Figure 4. The 24 Lineaje AI TARs, Apr 27 – Oct 8, 2026, mapped to the AI Kill Chain
Read across a row to follow one attack, or down a column to see how often a stage appears. Four findings stand out:
17 of 26 needed no traditional exploit and no malware. The AI was simply behaving as designed.
25 of 26 hijacked the model's reasoning (stage 4), the stage legacy tools can't see.
On average, attacks passed through 7.1 stages. That means seven chances to break it.
Coding assistants were the top target (10 of 26), and data or credential theft the top goal (16 of 26).
Introducing UnifAI: guardrails built in, enforced at runtime
UnifAI is Lineaje's autonomous AI policy orchestrator. It works at build time and at runtime as one system.
At build time, UnifAI discovers, derives, and inserts.
Discovers every AI asset as it's built: models, agents, sub-agents, MCP servers, skills, prompts, RAG components, and tools. It maps them in an Agent Blueprint, a topology and dependency graph of the agent.
Derives security, compliance, and governance policies from a library of 76 policies, mapped to 18+ global AI acts and standards.
Inserts Autonomous Intercepts: policy enforcement points on model calls, MCP interactions, and tool invocations. UnifAI places them automatically in IDEs, source control, and pull requests, and a human approves each change.
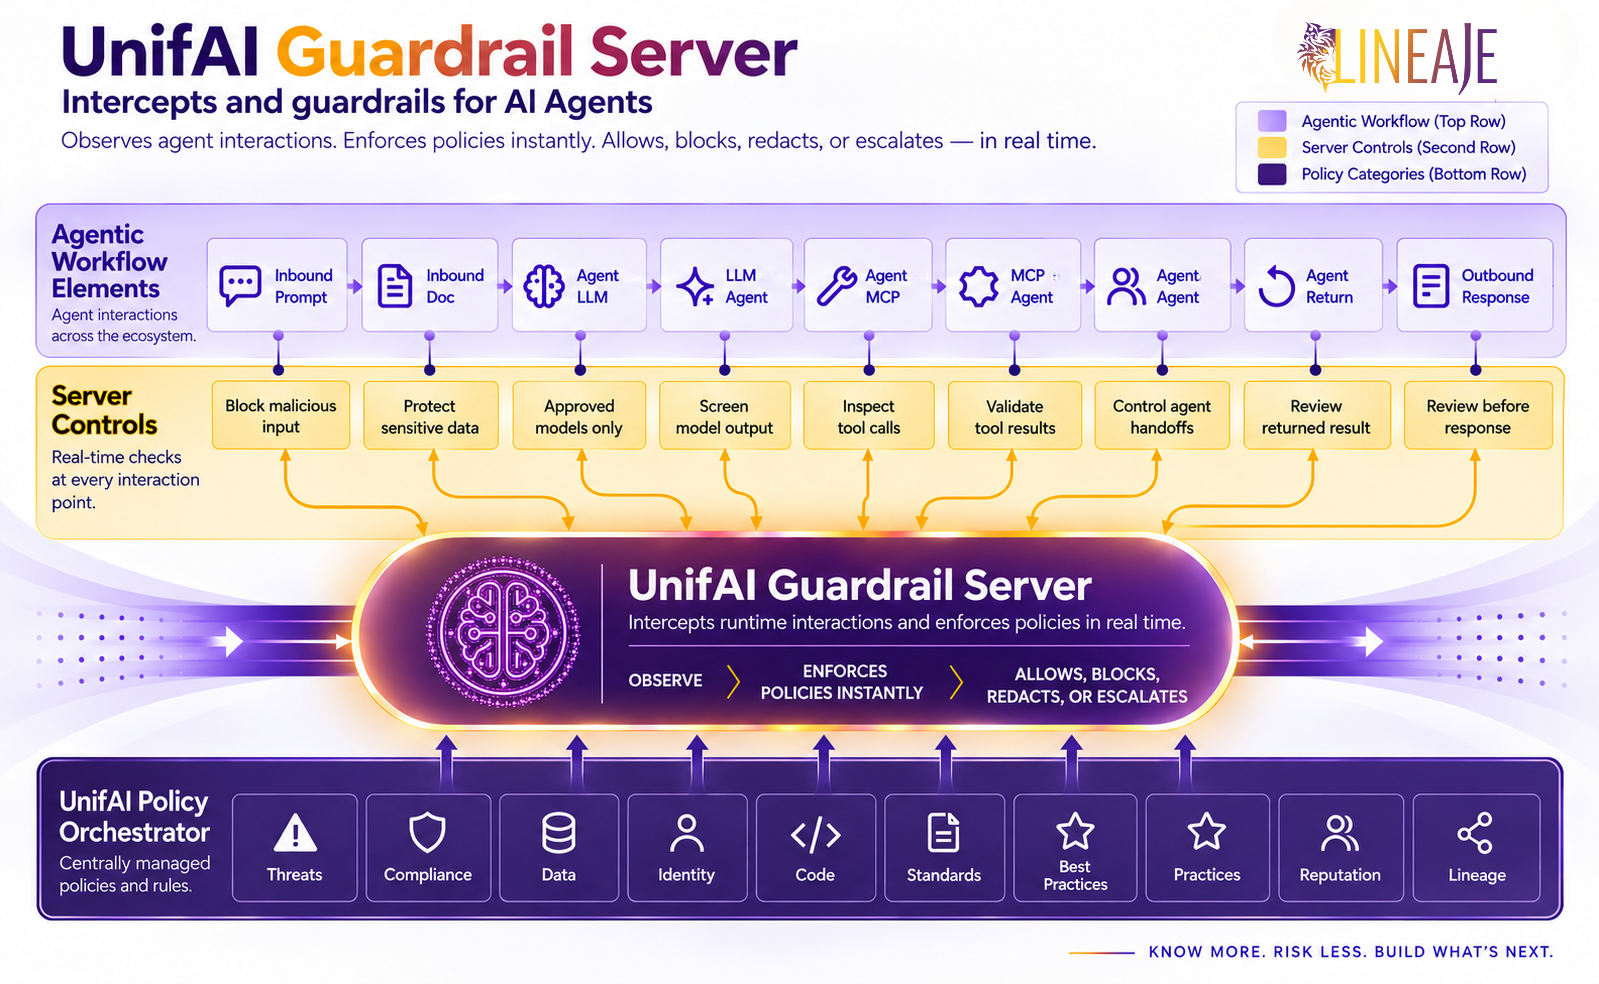
At runtime, the new UnifAI Guardrail Server defends. Every intercept calls the Guardrail Server, which checks the action in real time against the policies active at that moment and the 85 attack techniques of the AI Kill Chain. It can allow or block the action, require human approval, redact sensitive data, or restrict which tools and models the agent may use, all before execution continues.
Figure 5. The UnifAI Guardrail Server checks every step of the agent workflow, from inbound prompt to outbound response.
Two benefits accrue:
Policies change without redeploying agents. A central update takes effect on the next call, with no code change, fork or rebuild.
Build once, govern anywhere. Controls adapt by jurisdiction, business unit, customer, user, data classification or environment. The same agent can meet EU rules in Frankfurt and CERT-In rules in Mumbai.
Are your agents secure?
Lineaje's AI Labs analyzes each attack, maps them to every AI Kill Chain technique, and drives policies that break those attacks: 85 technique mappings across all 10 stages, covered by 61 policies. Every stage has several layers of defense, so an attacker who gets past one control meets the next. Few development teams could build this on their own. Developers are not threat experts.
Pick a couple of the AI TARS listed below to understand if your agents would be immune to these specific attacks.
Salesforce Agentforce and Slack. Research (Zenity Labs); since fixed.
Instructions planted through a public web-to-lead form sit in the CRM until an employee asks Agentforce about the lead. The agent then leaks CRM data through DNS lookups and posts phishing links into Slack under its own name.
Inspect CRM and other ingested content for embedded instructions, enforce URL allowlists on canonicalized URLs, and require confirmation for agent messages and other write actions.
Meta Muse macOS agent. Research (Patrick Wardle); since hot-fixed.
Local malware rewrites an unprotected setting so the agent's dictation runs through an attacker's server, which injects instructions, steals the session token and uses the agent's permissions to write files and take pictures.
Lock down the agent's trusted endpoints and configuration, verify where every instruction came from, and require confirmation for sensitive actions.
AI coding assistant at a SaaS provider. In the wild (Mandiant).
Attackers hijacked a coding-assistant session, which recommended a poisoned PyPI package. Its infostealer took GitHub tokens, and the Shai-Hulud worm spread across about 100 internal repositories.
Screen every AI-recommended dependency before install, route packages through approved repositories, and keep tokens away from assistant processes.
AI coding assistants and MCP packages. In the wild.
Trojanized repos and packages plant instructions in .claude/, .cursor/ and .vscode/ folders. Assistants then run attacker commands, steal CI/CD tokens and publish more poisoned packages.
Strip hidden prompts from source and config files, block malicious packages, and restrict the agent's tools and outbound destinations.
A prompt hidden in a README gives the attacker a reverse shell and persistence.
Authorize every tool action, harden execution, and protect shell configuration.
What makes this approach different
Built in, enforced at runtime. Intercepts go into the code, and the Guardrail Server acts on them in real time, faster than any SOC can respond.
One framework from threat intel to control. AI TARs, scanner findings and UnifAI policies all speak the language of the AI Kill Chain.
The AI supply chain, covered. The Skill Scanner, MCP scanner and the Malicious Open-Source Software Scanner stop poisoned skills, MCP servers and packages before an agent loads them.
Compliance as a by-product. Policies map to the NIST AI RMF, the EU AI Act, OWASP's LLM and Agentic Top 10s, ISO/IEC 42001, India's CERT-In AI Blueprint, with 25 standards in all (The State of AI Compliance Coverage). More in our next post.
Deploy anywhere. SaaS, public or private cloud, hybrid, on-premises or air-gapped.
The mandate: govern goals, authority, and memory
AI failures come from normal system behavior with too little control over goals, authority, and memory. Security built to find broken code won't catch software working as designed for the wrong person. Ask your team three questions this quarter:
What AI do we actually run? Every model, agent, MCP server, and skill, including the ones added last week.
Where does each agent get its authority? From a system of record, or from the last text it read?
Which kill chain stages can we block while the agent runs? And which can we only see afterward?
Map one agent to the AI Kill Chain and see where it breaks.
UnifAI: Secure AI. Govern AI. Continuously.
Agents will soon write more code than your developers and act on authority no one reviewed. UnifAI puts you back in control. It discovers every AI asset you run, builds guardrails into agents as they are written, and enforces them at runtime against all 85 techniques of the AI Kill Chain, in every jurisdiction where your agents operate.
Build your agents once. Secure them everywhere.
AI should optimize execution, not define authority. UnifAI makes sure it can't.
CTA: Subscribe to the weekly AI Threat Analysis Reports, or book a UnifAI kill chain assessment of one agentic application.
Sources
IBM, "Cost of a Data Breach Report 2025," July 30, 2025. newsroom.ibm.com
Fast Company, "Google CEO says 75% of the company's code is AI-generated," April 2026. fastcompany.com
Statista, "Number of active AI agents worldwide, 2025–2030," updated March 3, 2026. statista.com
SlashData, "Global developer population trends 2025." slashdata.co
Gartner, "Gartner Predicts 40% of Enterprise Apps Will Feature Task-Specific AI Agents by 2026," Aug 26, 2025. gartner.com
Verizon, "2026 Data Breach Investigations Report," May 19, 2026. verizon.com
The Hacker News, "Mini Shai-Hulud Worm Compromises TanStack, Mistral AI, Guardrails AI & More Packages," May 2026. thehackernews.com
OWASP, "Top 10 for Agentic Applications," Dec 9, 2025. genai.owasp.org
Goodwin, "EU AI Act Transparency Obligations Now in Force," Aug 3, 2026. goodwinlaw.com
Lineaje, "The AI Kill Chain: A Modern Security Framework to Identify, Prevent, and Mitigate AI-Driven and Agentic Threats," white paper, 2026. lineaje.com